Campus Networking
Secure, resilient switching for enterprise campuses and office environments.
Explore Campus Networking Solutions →Explore networking solutions for secure, high-performance connectivity across campus, data centre, wireless, WAN, industrial and cloud-managed environments.
Secure, resilient switching for enterprise campuses and office environments.
Explore Campus Networking Solutions →High-performance networking for modern data centres and AI infrastructure.
Explore Data Centre Networking Solutions →Enterprise wireless connectivity for secure, high-performance access.
Explore Wireless Solutions →Reliable connectivity for enterprise WANs, branch offices and industrial environments.
Explore WAN & Edge Solutions →Simplify network operations with cloud management, automation and visibility.
Explore Network Management Solutions →Secure users, sites and applications with modern connectivity and zero trust.
Explore Secure Access Solutions →Protect, monitor and optimise your network with enterprise security and analytics.
Explore Network Security Solutions →End-to-end networking services from design to deployment and optimisation.
Pre-configured switches, routers, wireless infrastructure and security appliances delivered ready for deployment, reducing installation time and ensuring consistency.
Reliable rack, blade and tower servers for demanding enterprise workloads.
Explore Enterprise Server Solutions →Optimised compute for AI, HPC, analytics and mission-critical applications.
Explore AI & HPC Solutions →Simplify and scale with compute, storage and virtualisation solutions.
Explore Virtualisation & HCI Solutions →Compact, rugged and efficient compute for edge and remote environments.
Explore Edge Compute Solutions →Flexible consumption models and private cloud solutions to modernise your IT.
Explore Hybrid Cloud Solutions →Manage, monitor and automate your compute environment with confidence.
Explore Infrastructure Management Solutions →Maximise value and extend the life of your compute investments.
End-to-end services to design, deploy and optimise your compute environment.
We pre-configure, test and validate your servers so they're ready to deploy from day one.
High-performance, scalable storage for critical enterprise workloads.
Explore Enterprise Storage Solutions →Flexible and cost-effective storage for growing businesses.
Entry & Midrange Storage Solutions →High-throughput storage for AI, HPC and data-intensive workloads.
AI & High-Performance Storage Solutions →Protect your data and ensure business continuity with trusted solutions.
Backup & Disaster Recovery Solutions →Secure, cost-efficient storage for long-term data retention.
Archive & Retention Storage Solutions →Intelligent management and automation for your storage infrastructure.
Storage Management Solutions →Maximise value and extend the life of your storage investments.
Explore Storage Lifecycle Services →End-to-end storage services from design to deployment and optimisation.
Storage systems configured and validated before delivery, ready for faster, smoother deployment.
Enterprise AI systems built for the most demanding workloads.
Explore AI Infrastructure Solutions →Powerful GPUs for training, HPC and inference workloads.
Explore GPU Compute Solutions →Deploy inference at scale and bring AI to the edge.
Explore AI Inference Solutions →Accelerate data movement and offload to boost performance.
Explore Data Processing Solutions →High-performance storage for AI training and inference.
Explore AI Storage Solutions →Comprehensive software and tools to build AI solutions.
Explore AI Platform Solutions →Expert services to design, deploy and optimise AI infrastructure.
We assess your current infrastructure, including GPU compute, networking and storage, to identify gaps and recommend the right AI architecture for your needs.
Explore data centre infrastructure solutions that keep critical environments powered, cooled, monitored and protected, from core facilities to distributed edge sites.
Resilient UPS and power distribution for critical data centre and enterprise environments.
Power Infrastructure Solutions →Rack, enclosure and power distribution foundations for organised infrastructure deployment.
Explore Rack Infrastructure Solutions →Air and liquid cooling approaches for resilient, high-density data centre environments.
Explore Cooling Solutions →Compact and rugged infrastructure for distributed, remote and operational sites.
Explore Edge Infrastructure Solutions →Centralised tools for monitoring, managing and optimising data centre power infrastructure.
Infrastructure Management Solutions →Visibility into environmental conditions, facility risk and distributed infrastructure health.
Environmental Monitoring Solutions →Maintenance and battery support to keep UPS platforms available throughout their lifecycle.
Explore UPS Lifecycle Services →Specialist design, deployment and assessment support for data centre power and cooling infrastructure.
We assess your infrastructure across power, compute, cooling and storage to identify gaps and constraints, then recommend the right architecture.
Specialist power, cooling and infrastructure knowledge.
From design and deployment to maintenance and optimisation.
Responsive support from experienced infrastructure specialists.
Improve efficiency, reduce risk and extend infrastructure life.
Speak to our specialists to find the right solution.
Contact a Specialist >
Secure, scalable and intelligent networking solutions for campus, branch, data centre and service provider environments.
Explore networking solutions →High-performance compute solutions designed to accelerate workloads from virtualisation to AI and HPC.
Explore compute solutions →
Genuine Cisco refurbished hardware with full warranty options, significant cost savings and a more sustainable approach to IT.
Expert technical support, software updates and advanced hardware replacement to help keep your Cisco infrastructure available and performing reliably.
Certified Cisco expertise, established vendor relationships and access to Cisco partner programmes and resources.
We design Cisco solutions around your workloads, security requirements, performance and future growth.
Get guidance on licensing, subscriptions, support coverage and long-term lifecycle requirements.
Compare new and genuine Cisco Refresh infrastructure around budget, lifecycle and project requirements.
Structured planning and deployment reduce complexity, project risk and pressure on your internal team.
Work directly with UK specialists who remain accountable throughout your Cisco project.
Industry-leading compute solutions built for performance, reliability and scalability.
Explore server solutions →
Intelligent storage solutions designed to protect, manage and accelerate your data.
Explore storage solutions →
Secure, AI-powered networking solutions for campus, branch and data centre environments.
Explore Aruba solutions →
HPE GreenLake brings cloud-like flexibility to your infrastructure, helping you manage compute, storage, networking and hybrid cloud environments through a unified platform.
Expert technical support, proactive guidance and hardware assistance to help keep your HPE infrastructure available, supported and performing reliably.
Accredited HPE expertise, established vendor relationships and access to HPE programmes.
We size HPE infrastructure around performance, capacity, resilience and growth.
Structured planning and deployment reduce complexity and pressure on your internal team.
We help identify the right pricing, programmes and commercial options for your project.
Compare new and refurbished HPE infrastructure around lifecycle, budget and requirements.
Work directly with UK specialists who remain accountable throughout your project.
Work with a HPE Juniper Partner for expert guidance across switching, routing, wireless, security and Mist AI – helping you improve performance, visibility and network operations.
AI-native network assurance and automation for wired, wireless, WAN and security environments, with proactive insights powered by Marvis.
Technical support, software updates and hardware replacement services to help keep your Juniper network infrastructure available and performing reliably.
Vendor-backed Juniper expertise, established relationships and access to partner programmes and resources.
We design around your switching, routing, wireless, security and scalability requirements.
Use Mist AI, Marvis and automation to simplify operations and improve network visibility.
We help identify suitable Juniper pricing, programmes and commercial options for your project.
Structured planning and deployment reduce implementation risk and pressure on your internal team.
We help manage support coverage, renewals and refresh planning throughout your Juniper lifecycle.
We supply NVIDIA products, sourced through certified UK distribution channels. Our experts build high-performance AI, GPU and supercomputing infrastructure around your workloads, performance requirements and data centre environment.
Enterprise AI software for developing, deploying and managing production AI workloads with NVIDIA frameworks, tools and optimised software.
Technical support, software updates and hardware assistance to help keep your NVIDIA AI, GPU and networking infrastructure available and supported.
NVIDIA solutions sourced from official distribution channels.
We turn workload, performance and capacity requirements into a practical infrastructure design.
We align NVIDIA with the right compute, storage, networking, power and cooling infrastructure.
Our extensive network helps your business source high-demand GPUs and infrastructure with greater confidence.
Our certified UK engineers remain accountable throughout planning and delivery.
We help manage procurement, financing, support and future refresh requirements around your investment.
Work with a Dell Technologies Partner for expert guidance across compute, storage, data protection and APEX – helping you simplify infrastructure and improve resilience.
Dell PowerEdge servers and compute platforms built for virtualisation, business-critical applications, AI, HPC and modern data centre workloads.
Explore Dell compute →Dell storage and data protection platforms for primary storage, backup, recovery and scalable enterprise data management.
Explore Dell storage →
Flexible infrastructure and as-a-service solutions for deploying, managing and scaling compute, storage and cloud resources across your IT environment.
Technical support, proactive assistance and hardware expertise to help keep your Dell compute, storage and data centre infrastructure available and supported.
We are a trusted Dell partner, providing genuine solutions, specialist guidance and dependable project support.
We align Dell infrastructure with your business goals, technical priorities and future growth.
We size compute and storage around your applications, performance, capacity and resilience requirements.
Structured planning and implementation help reduce complexity, project risk and demands on your internal team.
We help you plan capacity, expansion and refresh cycles before infrastructure becomes a constraint.
Optimisation, lifecycle support and informed refresh planning help you get more from your Dell investment.
Protect your users, networks and data with integrated Fortinet security across branch, campus, data centre and cloud environments.
Flexible, points-based licensing that lets you scale Fortinet services around changing workloads, deployments and business requirements.
Fortinet technical support, firmware updates and hardware replacement services to help keep your security infrastructure protected and available.
Trusted Fortinet expertise, established vendor relationships and access to partner programmes and resources.
We design Fortinet solutions around your users, applications, infrastructure and security requirements.
Get guidance on hardware, subscriptions, licensing and FortiFlex options for your requirements.
We review and optimise configurations to improve protection, visibility and operational efficiency.
Structured planning and deployment reduce implementation risk and pressure on your internal team.
We help manage support coverage, renewals and refresh planning throughout your Fortinet lifecycle.
Our storage specialists provide expert guidance across Everpure flash storage, Evergreen, support and lifecycle services — helping you simplify data management, modernise infrastructure and plan for long-term growth.
Modernise storage without disruptive refresh cycles, with continuous upgrades designed to extend infrastructure life and protect your investment.
Technical support, software updates and lifecycle assistance to help keep your Pure Storage infrastructure available, secure and performing reliably.
Vendor-backed expertise, programme access and support for solution planning and procurement.
We work with Everpure to help validate sizing, architecture and platform selection.
We help assess Evergreen models against your ownership, consumption and budget requirements.
We coordinate technical requirements and vendor resources throughout planning and implementation.
We align storage capacity, expansion and upgrade requirements with your future workloads.
We help manage support, renewals and upgrade planning throughout your storage lifecycle.
Work with a Supermicro reseller for expert guidance across enterprise compute, AI, GPU and HPC infrastructure — helping you deploy high-performance systems that are properly sized, pre-configured and ready for demanding workloads.
Receive deployment-ready Supermicro servers with component installation, firmware updates, configuration and testing completed before delivery.
Technical guidance, hardware support and lifecycle assistance to help keep your Supermicro infrastructure available, reliable and fit for changing workloads.
Supermicro solutions sourced from official distribution channels.
We size Supermicro platforms around performance, density, resilience and capacity requirements.
Plan high-performance infrastructure for AI training, inference, GPU computing and HPC.
Servers can arrive configured, updated and tested to reduce deployment time and internal workload.
Work directly with UK specialists who remain accountable throughout planning and delivery.
We help identify suitable configurations, pricing and purchasing options for your project.
Monitor power, cooling and data centre infrastructure with centralised visibility, alerts and remote management across distributed IT environments.
Proactive support, maintenance and lifecycle services to help keep your APC UPS infrastructure reliable, supported and ready for critical workloads.
Partner-backed APC expertise, established vendor relationships and access to programmes, resources and technical support.
We design UPS, power distribution, racks and cooling around your capacity, resilience and site requirements.
We assess load, runtime, redundancy and growth to help specify the right UPS infrastructure.
Improve visibility with monitoring, alerts and remote management across distributed IT environments.
We help identify suitable APC configurations, pricing and commercial options for your project.
We manage maintenance, support coverage, renewals and refresh planning throughout your APC lifecycle.
Speak to our specialists to find the right solution.
Contact a Specialist >Explore infrastructure solutions designed around your environment, workloads and business requirements — from networking and security to compute, storage, AI, cloud and data centre infrastructure.
Secure, scalable networking for campus, branch and WAN environments.
Protect your users, applications, data and infrastructure with layered enterprise security across your IT environment.
High-performance compute infrastructure for virtualisation, business-critical applications and demanding enterprise workloads.
Build the compute, networking and data foundations required for AI, analytics and accelerated workloads.
Protect, manage and recover critical business data with resilient enterprise storage and data protection infrastructure.
Build flexible private and hybrid cloud environments around your applications, workloads and operating requirements.
Connect industrial, OT and edge environments with resilient infrastructure designed for demanding and distributed sites.
Power, cool and manage critical data centre infrastructure for resilience, efficiency and future growth.
Explore networking solutions for secure, high-performance connectivity across campus, data centre, wireless, WAN, industrial and cloud-managed environments.
Secure, resilient switching for enterprise campuses and office environments.
Explore Campus Networking Solutions →High-performance networking for modern data centres and AI infrastructure.
Explore Data Centre Networking Solutions →Enterprise wireless connectivity for secure, high-performance access.
Explore Wireless Solutions →Reliable connectivity for enterprise WANs, branch offices and industrial environments.
Explore WAN & Edge Solutions →Simplify network operations with cloud management, automation and visibility.
Explore Network Management Solutions →Secure users, sites and applications with modern connectivity and zero trust.
Explore Secure Access Solutions →Protect, monitor and optimise your network with enterprise security and analytics.
Explore Network Security Solutions →End-to-end networking services from design to deployment and optimisation.
Pre-configured switches, routers, wireless infrastructure and security appliances delivered ready for deployment, reducing installation time and ensuring consistency.
Reliable rack, blade and tower servers for demanding enterprise workloads.
Explore Enterprise Server Solutions →Optimised compute for AI, HPC, analytics and mission-critical applications.
Explore AI & HPC Solutions →Simplify and scale with compute, storage and virtualisation solutions.
Explore Virtualisation & HCI Solutions →Compact, rugged and efficient compute for edge and remote environments.
Explore Edge Compute Solutions →Flexible consumption models and private cloud solutions to modernise your IT.
Explore Hybrid Cloud Solutions →Manage, monitor and automate your compute environment with confidence.
Explore Infrastructure Management Solutions →Maximise value and extend the life of your compute investments.
End-to-end services to design, deploy and optimise your compute environment.
We pre-configure, test and validate your servers so they're ready to deploy from day one.
High-performance, scalable storage for critical enterprise workloads.
Explore Enterprise Storage Solutions →Flexible and cost-effective storage for growing businesses.
Entry & Midrange Storage Solutions →High-throughput storage for AI, HPC and data-intensive workloads.
AI & High-Performance Storage Solutions →Protect your data and ensure business continuity with trusted solutions.
Backup & Disaster Recovery Solutions →Secure, cost-efficient storage for long-term data retention.
Archive & Retention Storage Solutions →Intelligent management and automation for your storage infrastructure.
Storage Management Solutions →Maximise value and extend the life of your storage investments.
Explore Storage Lifecycle Services →End-to-end storage services from design to deployment and optimisation.
Storage systems configured and validated before delivery, ready for faster, smoother deployment.
Enterprise AI systems built for the most demanding workloads.
Explore AI Infrastructure Solutions →Powerful GPUs for training, HPC and inference workloads.
Explore GPU Compute Solutions →Deploy inference at scale and bring AI to the edge.
Explore AI Inference Solutions →Accelerate data movement and offload to boost performance.
Explore Data Processing Solutions →High-performance storage for AI training and inference.
Explore AI Storage Solutions →Comprehensive software and tools to build AI solutions.
Explore AI Platform Solutions →Expert services to design, deploy and optimise AI infrastructure.
We assess your current infrastructure, including GPU compute, networking and storage, to identify gaps and recommend the right AI architecture for your needs.
Explore data centre infrastructure solutions that keep critical environments powered, cooled, monitored and protected, from core facilities to distributed edge sites.
Resilient UPS and power distribution for critical data centre and enterprise environments.
Power Infrastructure Solutions →Rack, enclosure and power distribution foundations for organised infrastructure deployment.
Explore Rack Infrastructure Solutions →Air and liquid cooling approaches for resilient, high-density data centre environments.
Explore Cooling Solutions →Compact and rugged infrastructure for distributed, remote and operational sites.
Explore Edge Infrastructure Solutions →Centralised tools for monitoring, managing and optimising data centre power infrastructure.
Infrastructure Management Solutions →Visibility into environmental conditions, facility risk and distributed infrastructure health.
Environmental Monitoring Solutions →Maintenance and battery support to keep UPS platforms available throughout their lifecycle.
Explore UPS Lifecycle Services →Specialist design, deployment and assessment support for data centre power and cooling infrastructure.
We assess your infrastructure across power, compute, cooling and storage to identify gaps and constraints, then recommend the right architecture.
Specialist power, cooling and infrastructure knowledge.
From design and deployment to maintenance and optimisation.
Responsive support from experienced infrastructure specialists.
Improve efficiency, reduce risk and extend infrastructure life.
Speak to our specialists to find the right solution.
Contact a Specialist >
Secure, scalable and intelligent networking solutions for campus, branch, data centre and service provider environments.
Explore networking solutions →High-performance compute solutions designed to accelerate workloads from virtualisation to AI and HPC.
Explore compute solutions →
Genuine Cisco refurbished hardware with full warranty options, significant cost savings and a more sustainable approach to IT.
Expert technical support, software updates and advanced hardware replacement to help keep your Cisco infrastructure available and performing reliably.
Certified Cisco expertise, established vendor relationships and access to Cisco partner programmes and resources.
We design Cisco solutions around your workloads, security requirements, performance and future growth.
Get guidance on licensing, subscriptions, support coverage and long-term lifecycle requirements.
Compare new and genuine Cisco Refresh infrastructure around budget, lifecycle and project requirements.
Structured planning and deployment reduce complexity, project risk and pressure on your internal team.
Work directly with UK specialists who remain accountable throughout your Cisco project.
Industry-leading compute solutions built for performance, reliability and scalability.
Explore server solutions →
Intelligent storage solutions designed to protect, manage and accelerate your data.
Explore storage solutions →
Secure, AI-powered networking solutions for campus, branch and data centre environments.
Explore Aruba solutions →
HPE GreenLake brings cloud-like flexibility to your infrastructure, helping you manage compute, storage, networking and hybrid cloud environments through a unified platform.
Expert technical support, proactive guidance and hardware assistance to help keep your HPE infrastructure available, supported and performing reliably.
Accredited HPE expertise, established vendor relationships and access to HPE programmes.
We size HPE infrastructure around performance, capacity, resilience and growth.
Structured planning and deployment reduce complexity and pressure on your internal team.
We help identify the right pricing, programmes and commercial options for your project.
Compare new and refurbished HPE infrastructure around lifecycle, budget and requirements.
Work directly with UK specialists who remain accountable throughout your project.
Work with a HPE Juniper Partner for expert guidance across switching, routing, wireless, security and Mist AI – helping you improve performance, visibility and network operations.
AI-native network assurance and automation for wired, wireless, WAN and security environments, with proactive insights powered by Marvis.
Technical support, software updates and hardware replacement services to help keep your Juniper network infrastructure available and performing reliably.
Vendor-backed Juniper expertise, established relationships and access to partner programmes and resources.
We design around your switching, routing, wireless, security and scalability requirements.
Use Mist AI, Marvis and automation to simplify operations and improve network visibility.
We help identify suitable Juniper pricing, programmes and commercial options for your project.
Structured planning and deployment reduce implementation risk and pressure on your internal team.
We help manage support coverage, renewals and refresh planning throughout your Juniper lifecycle.
We supply NVIDIA products, sourced through certified UK distribution channels. Our experts build high-performance AI, GPU and supercomputing infrastructure around your workloads, performance requirements and data centre environment.
Enterprise AI software for developing, deploying and managing production AI workloads with NVIDIA frameworks, tools and optimised software.
Technical support, software updates and hardware assistance to help keep your NVIDIA AI, GPU and networking infrastructure available and supported.
NVIDIA solutions sourced from official distribution channels.
We turn workload, performance and capacity requirements into a practical infrastructure design.
We align NVIDIA with the right compute, storage, networking, power and cooling infrastructure.
Our extensive network helps your business source high-demand GPUs and infrastructure with greater confidence.
Our certified UK engineers remain accountable throughout planning and delivery.
We help manage procurement, financing, support and future refresh requirements around your investment.
Work with a Dell Technologies Partner for expert guidance across compute, storage, data protection and APEX – helping you simplify infrastructure and improve resilience.
Dell PowerEdge servers and compute platforms built for virtualisation, business-critical applications, AI, HPC and modern data centre workloads.
Explore Dell compute →Dell storage and data protection platforms for primary storage, backup, recovery and scalable enterprise data management.
Explore Dell storage →
Flexible infrastructure and as-a-service solutions for deploying, managing and scaling compute, storage and cloud resources across your IT environment.
Technical support, proactive assistance and hardware expertise to help keep your Dell compute, storage and data centre infrastructure available and supported.
We are a trusted Dell partner, providing genuine solutions, specialist guidance and dependable project support.
We align Dell infrastructure with your business goals, technical priorities and future growth.
We size compute and storage around your applications, performance, capacity and resilience requirements.
Structured planning and implementation help reduce complexity, project risk and demands on your internal team.
We help you plan capacity, expansion and refresh cycles before infrastructure becomes a constraint.
Optimisation, lifecycle support and informed refresh planning help you get more from your Dell investment.
Protect your users, networks and data with integrated Fortinet security across branch, campus, data centre and cloud environments.
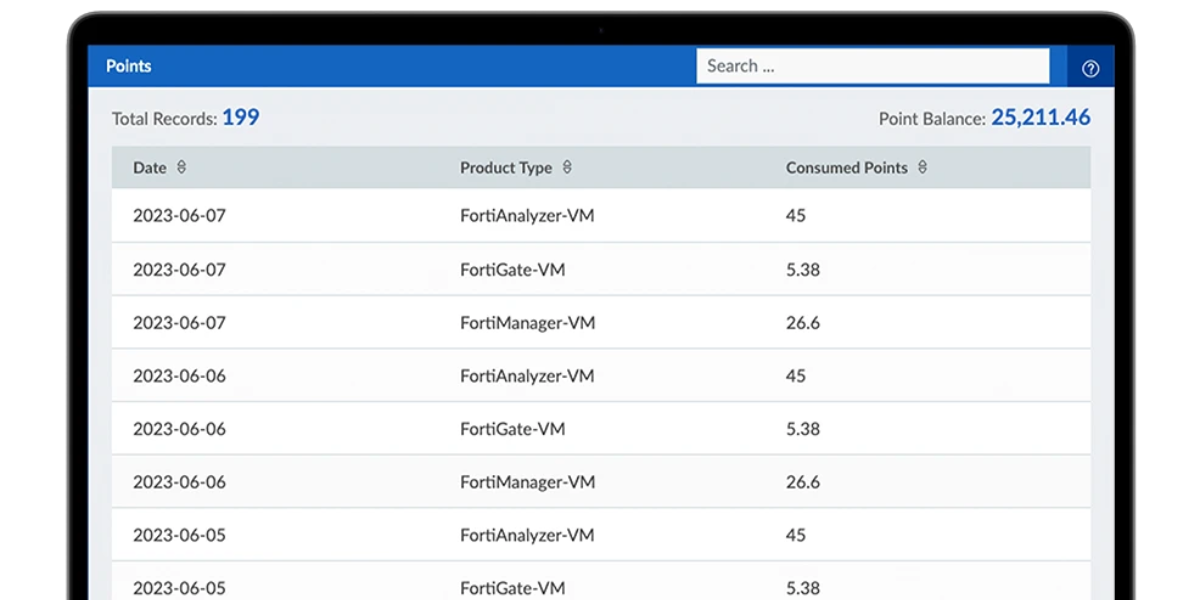
Flexible, points-based licensing that lets you scale Fortinet services around changing workloads, deployments and business requirements.
Fortinet technical support, firmware updates and hardware replacement services to help keep your security infrastructure protected and available.
Trusted Fortinet expertise, established vendor relationships and access to partner programmes and resources.
We design Fortinet solutions around your users, applications, infrastructure and security requirements.
Get guidance on hardware, subscriptions, licensing and FortiFlex options for your requirements.
We review and optimise configurations to improve protection, visibility and operational efficiency.
Structured planning and deployment reduce implementation risk and pressure on your internal team.
We help manage support coverage, renewals and refresh planning throughout your Fortinet lifecycle.
Our storage specialists provide expert guidance across Everpure flash storage, Evergreen, support and lifecycle services — helping you simplify data management, modernise infrastructure and plan for long-term growth.
Modernise storage without disruptive refresh cycles, with continuous upgrades designed to extend infrastructure life and protect your investment.
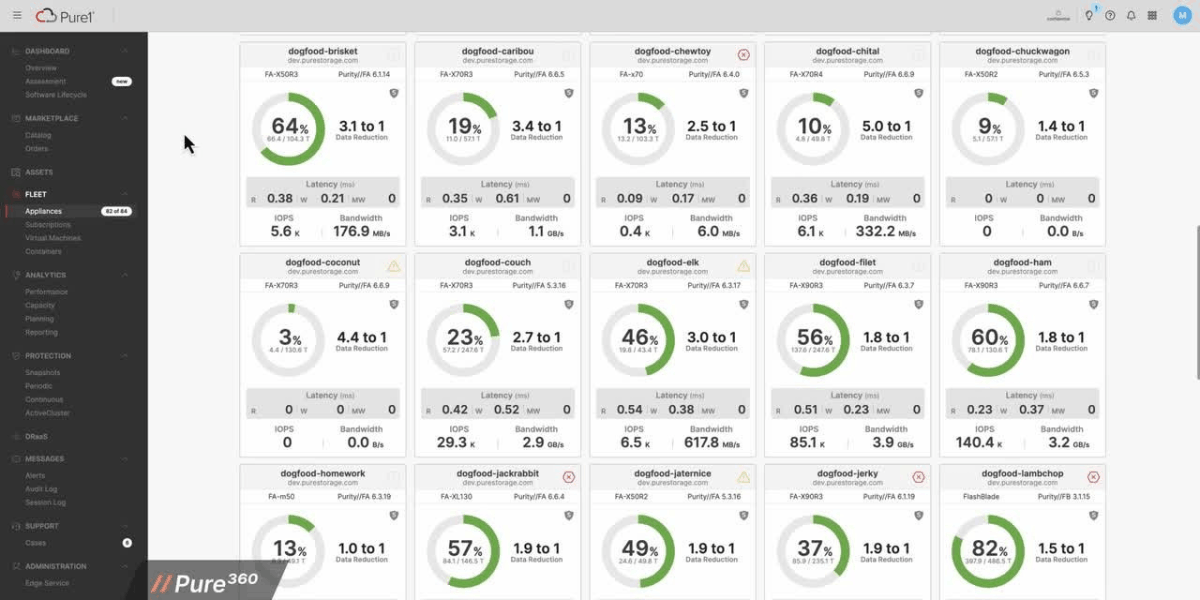
Technical support, software updates and lifecycle assistance to help keep your Pure Storage infrastructure available, secure and performing reliably.
Vendor-backed expertise, programme access and support for solution planning and procurement.
We work with Everpure to help validate sizing, architecture and platform selection.
We help assess Evergreen models against your ownership, consumption and budget requirements.
We coordinate technical requirements and vendor resources throughout planning and implementation.
We align storage capacity, expansion and upgrade requirements with your future workloads.
We help manage support, renewals and upgrade planning throughout your storage lifecycle.
Work with a Supermicro reseller for expert guidance across enterprise compute, AI, GPU and HPC infrastructure — helping you deploy high-performance systems that are properly sized, pre-configured and ready for demanding workloads.
Receive deployment-ready Supermicro servers with component installation, firmware updates, configuration and testing completed before delivery.
Technical guidance, hardware support and lifecycle assistance to help keep your Supermicro infrastructure available, reliable and fit for changing workloads.
Supermicro solutions sourced from official distribution channels.
We size Supermicro platforms around performance, density, resilience and capacity requirements.
Plan high-performance infrastructure for AI training, inference, GPU computing and HPC.
Servers can arrive configured, updated and tested to reduce deployment time and internal workload.
Work directly with UK specialists who remain accountable throughout planning and delivery.
We help identify suitable configurations, pricing and purchasing options for your project.
Monitor power, cooling and data centre infrastructure with centralised visibility, alerts and remote management across distributed IT environments.
Proactive support, maintenance and lifecycle services to help keep your APC UPS infrastructure reliable, supported and ready for critical workloads.
Partner-backed APC expertise, established vendor relationships and access to programmes, resources and technical support.
We design UPS, power distribution, racks and cooling around your capacity, resilience and site requirements.
We assess load, runtime, redundancy and growth to help specify the right UPS infrastructure.
Improve visibility with monitoring, alerts and remote management across distributed IT environments.
We help identify suitable APC configurations, pricing and commercial options for your project.
We manage maintenance, support coverage, renewals and refresh planning throughout your APC lifecycle.
Speak to our specialists to find the right solution.
Contact a Specialist >Explore infrastructure solutions designed around your environment, workloads and business requirements — from networking and security to compute, storage, AI, cloud and data centre infrastructure.
Secure, scalable networking for campus, branch and WAN environments.
Protect your users, applications, data and infrastructure with layered enterprise security across your IT environment.
High-performance compute infrastructure for virtualisation, business-critical applications and demanding enterprise workloads.
Build the compute, networking and data foundations required for AI, analytics and accelerated workloads.
Protect, manage and recover critical business data with resilient enterprise storage and data protection infrastructure.
Build flexible private and hybrid cloud environments around your applications, workloads and operating requirements.
Connect industrial, OT and edge environments with resilient infrastructure designed for demanding and distributed sites.
Power, cool and manage critical data centre infrastructure for resilience, efficiency and future growth.
This guide explains how a GPU health check finds the causes of instability and underperformance. We review utilisation, temperatures, memory, drivers and error events, then set out which fixes to prioritise.
A GPU Health Check is a technical review of GPU systems to determine whether hardware and supporting software are operating reliably and delivering expected performance. It examines utilisation, memory usage, temperatures, power behaviour, errors, drivers, firmware and workload behaviour.
Who it’s for
Organisations running GPU-accelerated AI, machine learning, rendering, simulation, analytics or HPC workloads, especially where systems are business-critical or performance has become inconsistent.
Common use cases
Understand GPU health, performance and usage so issues can be addressed before they affect critical workloads.
Find conditions reducing GPU workload performance so hardware, software or infrastructure constraints can be addressed.
Understand why accelerators are idle or underused and where existing GPU capacity can be used more effectively.
Identify errors, thermal issues and component degradation early before they develop into hardware failure.
Confirm drivers, firmware, system settings and supporting infrastructure are configured appropriately for stable operation.
Address reliability issues before they interrupt long-running AI, rendering or HPC workloads.
Use current health and utilisation evidence to judge when additional GPU or supporting infrastructure is needed.
GPU health checks commonly identify performance, stability and scaling issues across compute, cooling, software and interconnects.
Workloads, scheduling, software settings or supporting infrastructure may leave available GPU compute underused or idle.
High temperatures, restricted airflow or cooling problems can lower clock speeds and increase the risk of instability.
Limited GPU memory or uneven memory demand can cause out-of-memory errors, workload failures or reduced batch sizes.
Outdated, inconsistent or incompatible software components can lead to instability, unexpected errors or reduced functionality.
PCIe, NVLink, InfiniBand or Ethernet limits can restrict communication and prevent distributed GPU workloads scaling efficiently.
ECC errors, failing components or unstable links can indicate developing faults that reduce reliability or interrupt workloads.
We assess six key areas across the GPU environment, covering compute health, data supply, interconnects, facilities, software and operations.
We evaluate the GPU and surrounding infrastructure to identify where instability, low utilisation or degraded workload performance originates.
This health check identifies whether GPU issues originate in the accelerator, data path, network, facilities or software stack, and clarifies the remediation priorities.
Choose the approach based on whether issues are visible in telemetry, faults or workload behaviour.
Operational GPU environments with monitoring data available over time.
Requires reliable telemetry with enough historical coverage.
GPU systems showing faults, alerts, instability or degraded nodes.
A point-in-time check may miss intermittent faults.
Healthy GPU environments with poor throughput, latency or scaling efficiency.
Representative workloads and agreed performance targets are essential.
GPU estates with mixed nodes, recent changes or version concerns.
Configuration alignment should consider application dependencies.
The engagement follows a structured six-stage process, from scope and live GPU review through analysis, findings and a practical remediation plan.
You explain the performance concerns and the services or workloads affected. We confirm which GPU systems to assess and any access or maintenance limits that could shape the engagement.
We review GPU health and performance data while representative work is running. This shows whether the GPUs are constraining the workload or whether another part of the system is more likely to be involved.
We assess GPU condition alongside the supporting software to identify faults or mismatches. This helps explain reliability issues or slower-than-expected workload performance.
We use representative tests and workload results to judge whether the current GPUs are delivering the level of performance your teams need. This gives a clear view of whether the platform is meeting operational demand.
We connect the health and performance evidence to likely causes and show which workloads are affected. This makes it clearer whether the issue is GPU-related or driven by another system constraint.
We set out the changes to make, their priority and how to verify performance afterwards. This gives you a practical basis for restoring stability or maintaining the workload performance your services depend on.
Before the assessment begins, we will ask you to provide, share or arrange the information, access and documentation needed for the review.
Provide a complete list of GPU-equipped servers or nodes in scope, including GPU model, quantity, server model, location, cluster membership and asset identifiers.
Describe the GPU workloads, including applications, AI or HPC frameworks, model types, batch sizes, job schedules, concurrency and known performance symptoms.
Arrange read-only access to available GPU monitoring and telemetry sources covering utilisation, memory use, temperatures, power draw, clock behaviour, errors and interconnect activity.
Provide current GPU driver, accelerator software stack, firmware, BIOS and management-controller versions, plus any recent upgrade or rollback history.
Supply the current server and cluster configuration, including CPU, memory, storage, operating system, GPU topology, interconnects, network adapters and orchestration settings.
Share available historical utilisation, temperature, error, alert and performance data, plus previous benchmark results, incidents or support cases where these exist.
These principles guide how we assess GPU health and performance under real workloads, normal operating ranges and wider stack conditions.
We collect and review telemetry during representative or production workloads so utilisation, memory pressure, errors and performance are assessed in meaningful conditions.
We set normal ranges for utilisation, memory, temperature, power and throughput so expected workload variation can be separated from abnormal behaviour or degradation.
We compare GPU compute utilisation with memory use, power, workload activity and upstream dependencies to determine whether instability comes from the accelerator or elsewhere.
We review drivers, firmware, CUDA and supporting software against validated combinations to flag versions that may introduce instability, performance loss or support risk.
We review temperatures, fan behaviour, throttling events and cooling conditions to determine whether thermal pressure is affecting performance, reliability or component life.
We assess health trends alongside recent workload, firmware and infrastructure changes so developing faults, drift and recurring issues are not treated as isolated events.
Following the assessment, you receive documented GPU health findings, performance analysis, prioritised risks and practical remediation actions for the environment reviewed.
A technical overview of GPU utilisation, memory behaviour, temperatures, power, errors, driver and firmware state, system configuration and other collected evidence.
A clear record of observed utilisation, throughput, memory pressure, throttling, workload behaviour and bottlenecks, showing where GPU performance is being lost.
A prioritised record of identified faults, warnings, configuration concerns and operational risks, including likely impact and the systems or workloads affected.
Practical corrective actions for identified issues, including configuration changes, driver or firmware remediation, cooling improvements, workload tuning and component investigation.
We help IT teams assess GPU environments before making changes, so you can understand current performance, capacity, resilience and lifecycle concerns, and define the right next steps with confidence.
GPU Health Check
Tell us about your current environment, the issues you want to assess and any planned changes or projects. We’ll discuss the scope of the assessment and what you need it to establish.
Where the assessment identifies gaps or improvement opportunities, Steel City Consulting can support the next stage, from remediation and infrastructure design through to implementation and ongoing optimisation.
Address performance, capacity, resilience, configuration and lifecycle issues.
Turn findings into a practical target architecture and prioritised plan.
Select, size and implement infrastructure required to address identified needs.
Validate improvements and support future capacity, lifecycle and modernisation needs.
Need help with a GPU health check?
Speak to our team about your environment, assessment scope and the actions needed after the findings are reviewed.
GPU health findings often connect to platform design, capacity and cluster architecture; these guides provide the wider context for remediation and future planning.
Explore how GPU compute, storage, networking, data pipelines, power and cooling are designed together for production AI infrastructure.
Read the guideUnderstand how model, memory, concurrency, performance and growth requirements are converted into GPU and supporting infrastructure capacity.
Read the guideReview the practical deployment considerations for multi-GPU clusters, including node design, interconnects, storage, networking, power and cooling.
Read the guideReview the wider readiness factors that determine whether data, infrastructure, facilities, security and operations can support planned AI workloads.
Read the guideGPU health findings can feed into wider AI infrastructure remediation, server changes, interconnect improvements and ongoing monitoring.
Translate assessment findings into an integrated AI platform covering compute, GPU acceleration, storage, networking, management and supporting data-centre requirements.
Design Your AI Infrastructure ›Size, specify and supply GPU-accelerated server platforms around workload, memory, power, cooling and scalability requirements identified during the assessment.
Explore AI & GPU Servers ›Use high-bandwidth GPU interconnects where multi-GPU workload analysis shows that accelerator-to-accelerator communication is a material performance requirement.
Explore NVLink ›Implement centralised monitoring, telemetry and infrastructure management so health, capacity, performance and faults identified during the assessment can be tracked proactively.
Simplify Infrastructure Management ›A GPU health check is useful when performance, utilisation or reliability has changed and you need evidence before deciding whether to tune, repair or replace equipment.
It is particularly relevant when workloads are slower than expected, GPU use has fallen, or teams disagree about the cause. We compare the GPU with its host and supporting systems so the next action addresses the constraint rather than simply adding or replacing hardware.
The assessment compares GPU activity with host, storage, network and software performance to find where the workload is actually being held up.
A GPU can appear underused because it is waiting for data, CPU resources or another cluster node. We trace the evidence across those layers, then explain which constraint is affecting the workload and what should be investigated or changed first.
Low GPU utilisation can result from workload design, scheduling, host limits or slow data delivery, so utilisation needs to be assessed across the platform.
We compare periods of active GPU computation with the behaviour of the host and data path. This helps distinguish a configuration or scheduling issue from a capacity constraint and shows whether changes to the workload or infrastructure are likely to improve use.
We review GPU temperature, power behaviour and system conditions under load to identify whether thermal or electrical limits are reducing performance.
If limits are being reached, we examine whether the cause sits with cooling, server configuration, power delivery or the component itself. The findings help your team target the right remedy and avoid replacing hardware when an environmental or configuration change may be sufficient.
Yes, storage latency or network delays can leave GPUs waiting, so we examine data delivery and cluster communication alongside accelerator activity.
We look for idle periods that coincide with data access or communication between nodes, then trace those delays through storage and the interconnect. This helps establish whether improving the data path could deliver more value than adding GPUs.
We compare driver, firmware, CUDA and supporting software versions across systems to identify compatibility issues and inconsistencies linked to instability.
Differences between otherwise similar servers can help explain why faults are intermittent or isolated to particular workloads. We use the findings to distinguish software or versioning problems from hardware faults and establish a more consistent baseline for further troubleshooting.
Yes, the findings can separate issues that may be tuned from hardware faults, capacity limits and lifecycle risks that may justify repair or replacement.
The recommendation is based on the evidence gathered about configuration, workload behaviour and component condition. We explain what can remain in service, what needs remedial work and where replacement should be considered, giving your team a basis for prioritising spend and timing.
Most checks use telemetry, logs and read-only system information, so GPU workloads can usually continue while we assess the environment.
If stress testing or deeper diagnostics could affect production jobs, we agree the method, timing and safeguards with your team first. The assessment plan makes clear what information is needed and which activities, if any, require a maintenance window.
You will have an evidence-based view of the main performance or reliability issue, its likely cause and the actions worth prioritising.
We present the findings in terms of operational impact and practical next steps, such as tuning, remediation, capacity changes or refresh planning. This gives IT and the business a clearer basis for assigning work, setting timing and preparing a budget.
Yes, we can help turn the agreed findings into a plan and support the sourcing, implementation and ongoing optimisation of suitable GPU infrastructure.
We can work with your team to resolve configuration issues, plan hardware changes or assess the wider AI environment, keeping follow-on decisions tied to assessment evidence and supporting the platform through its lifecycle. Discuss the findings with our team.